Measuring the Unmeasurable: Evaluating Generative AI in Practice
Measuring the Unmeasurable: Evaluating Generative AI in Practice by Erin Pacquetet
Room 8 · Lunch Talk · 12:40-13:20
Summary
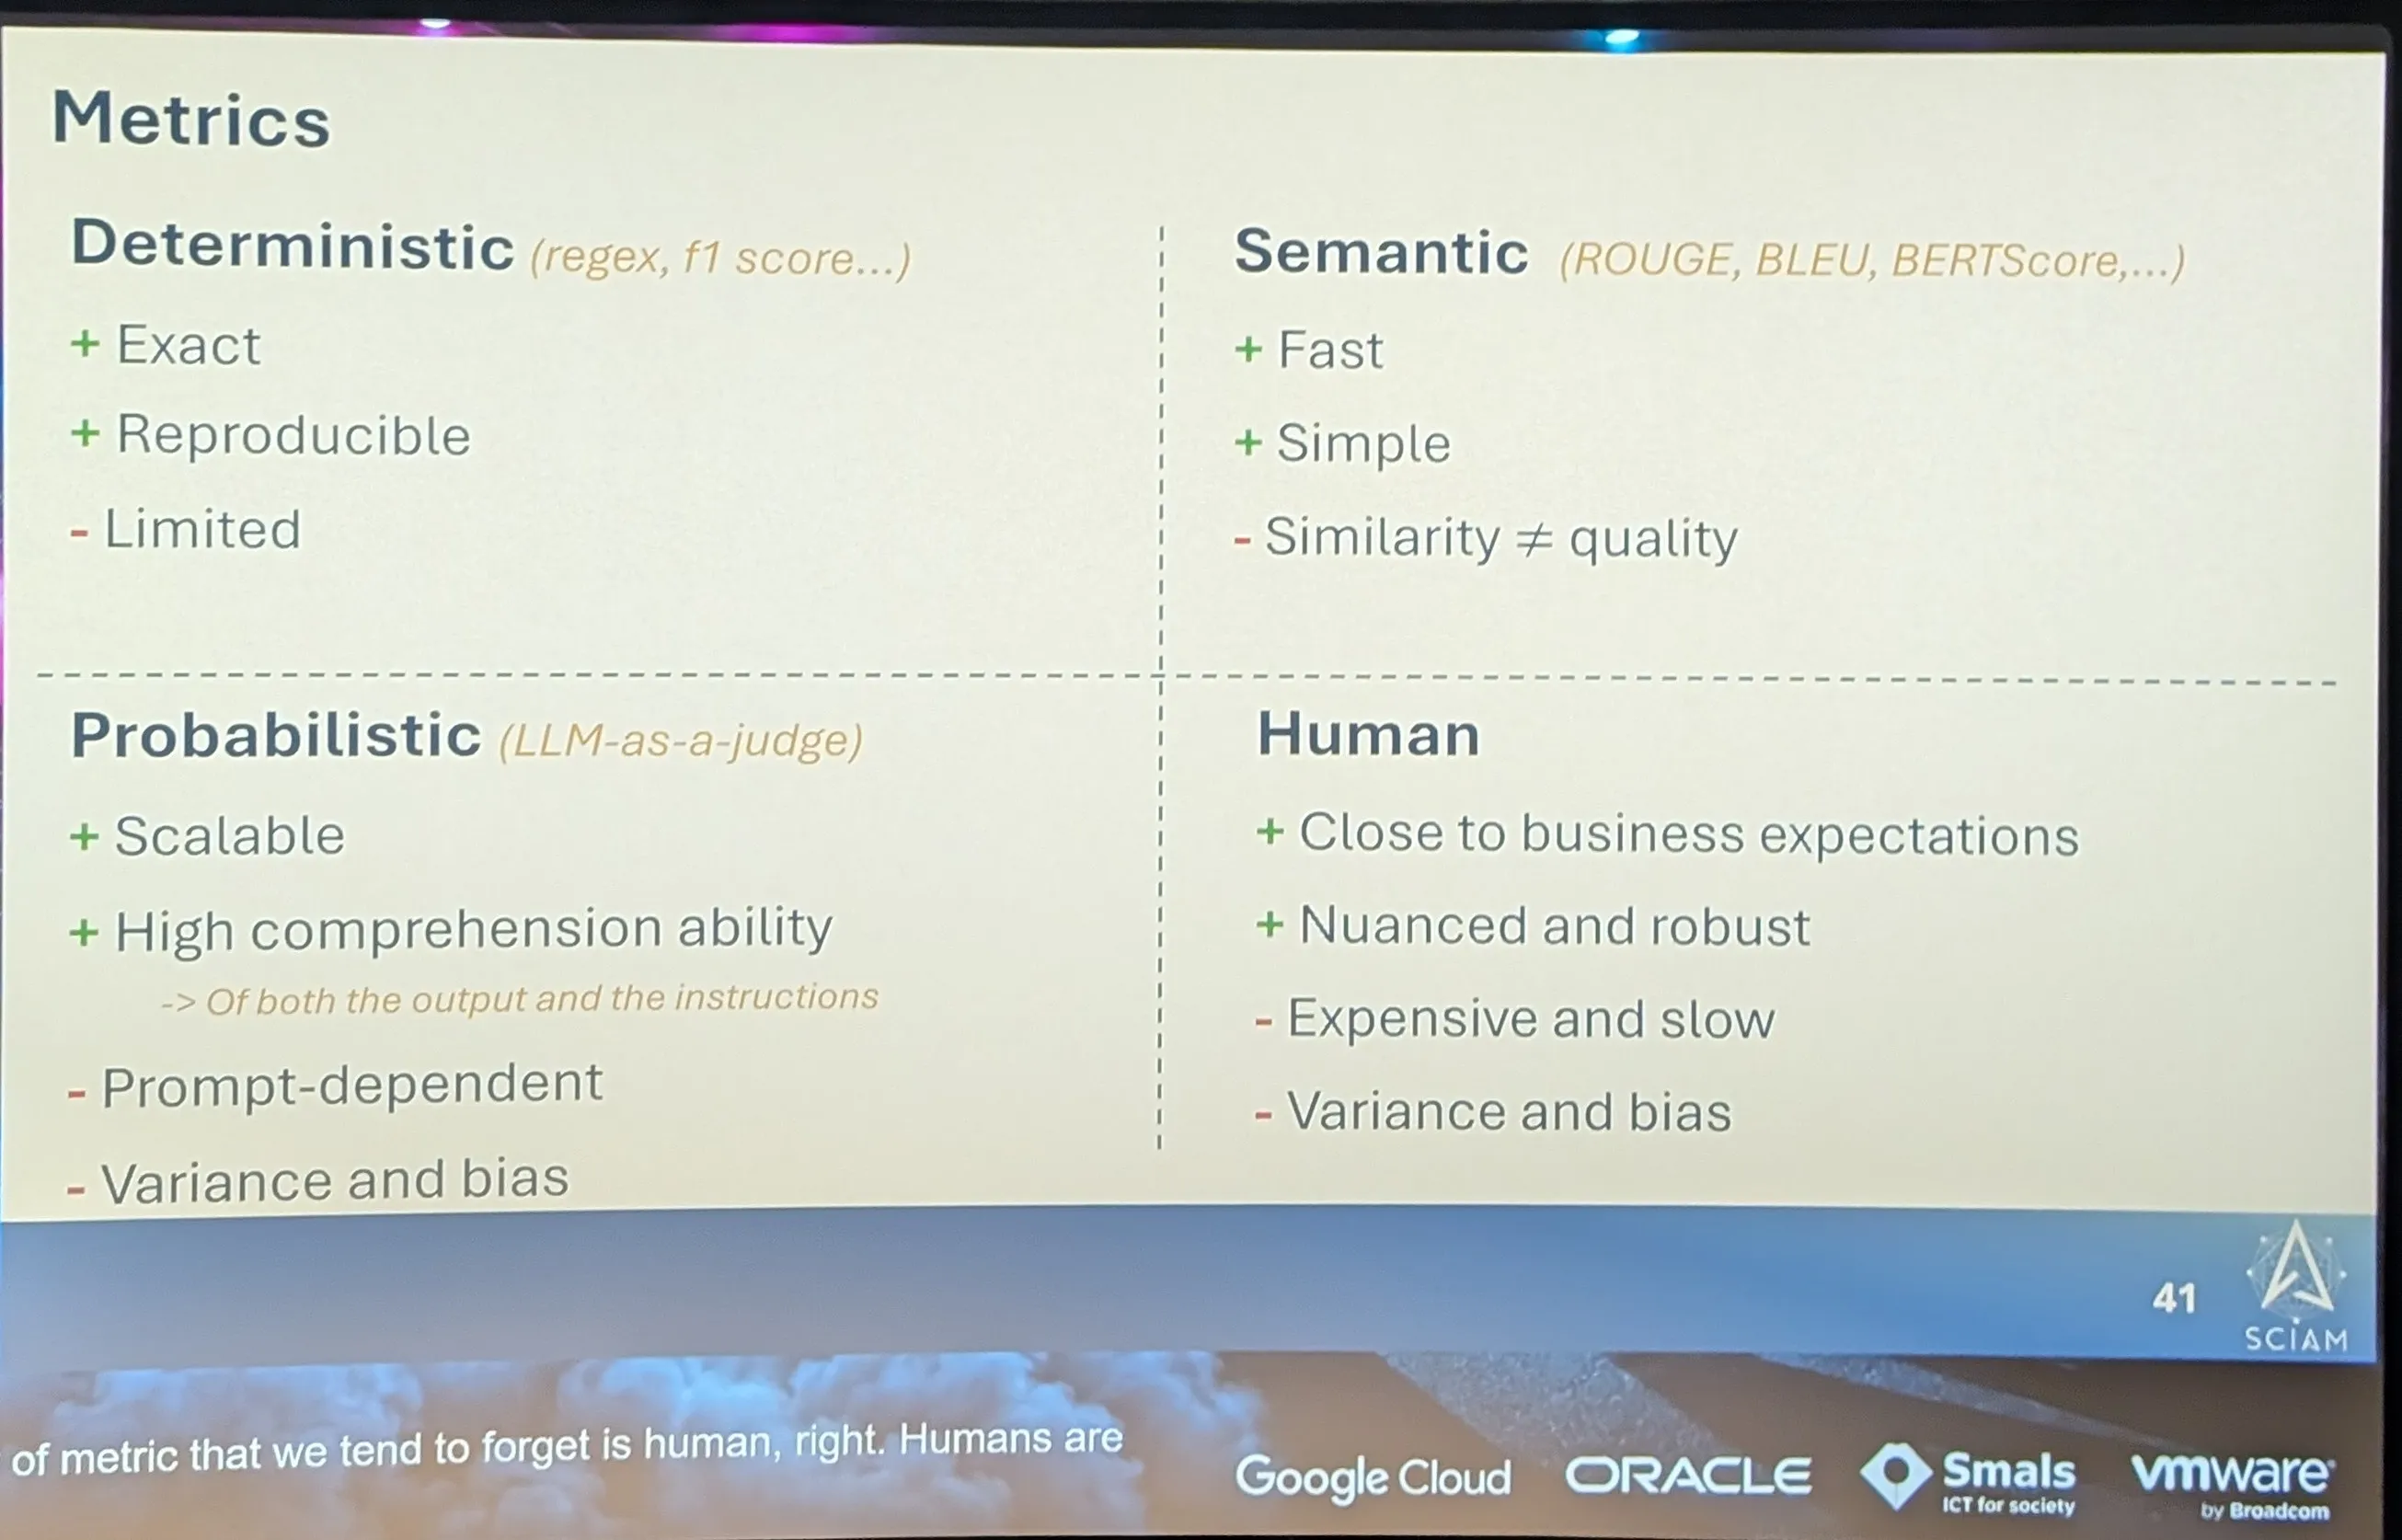
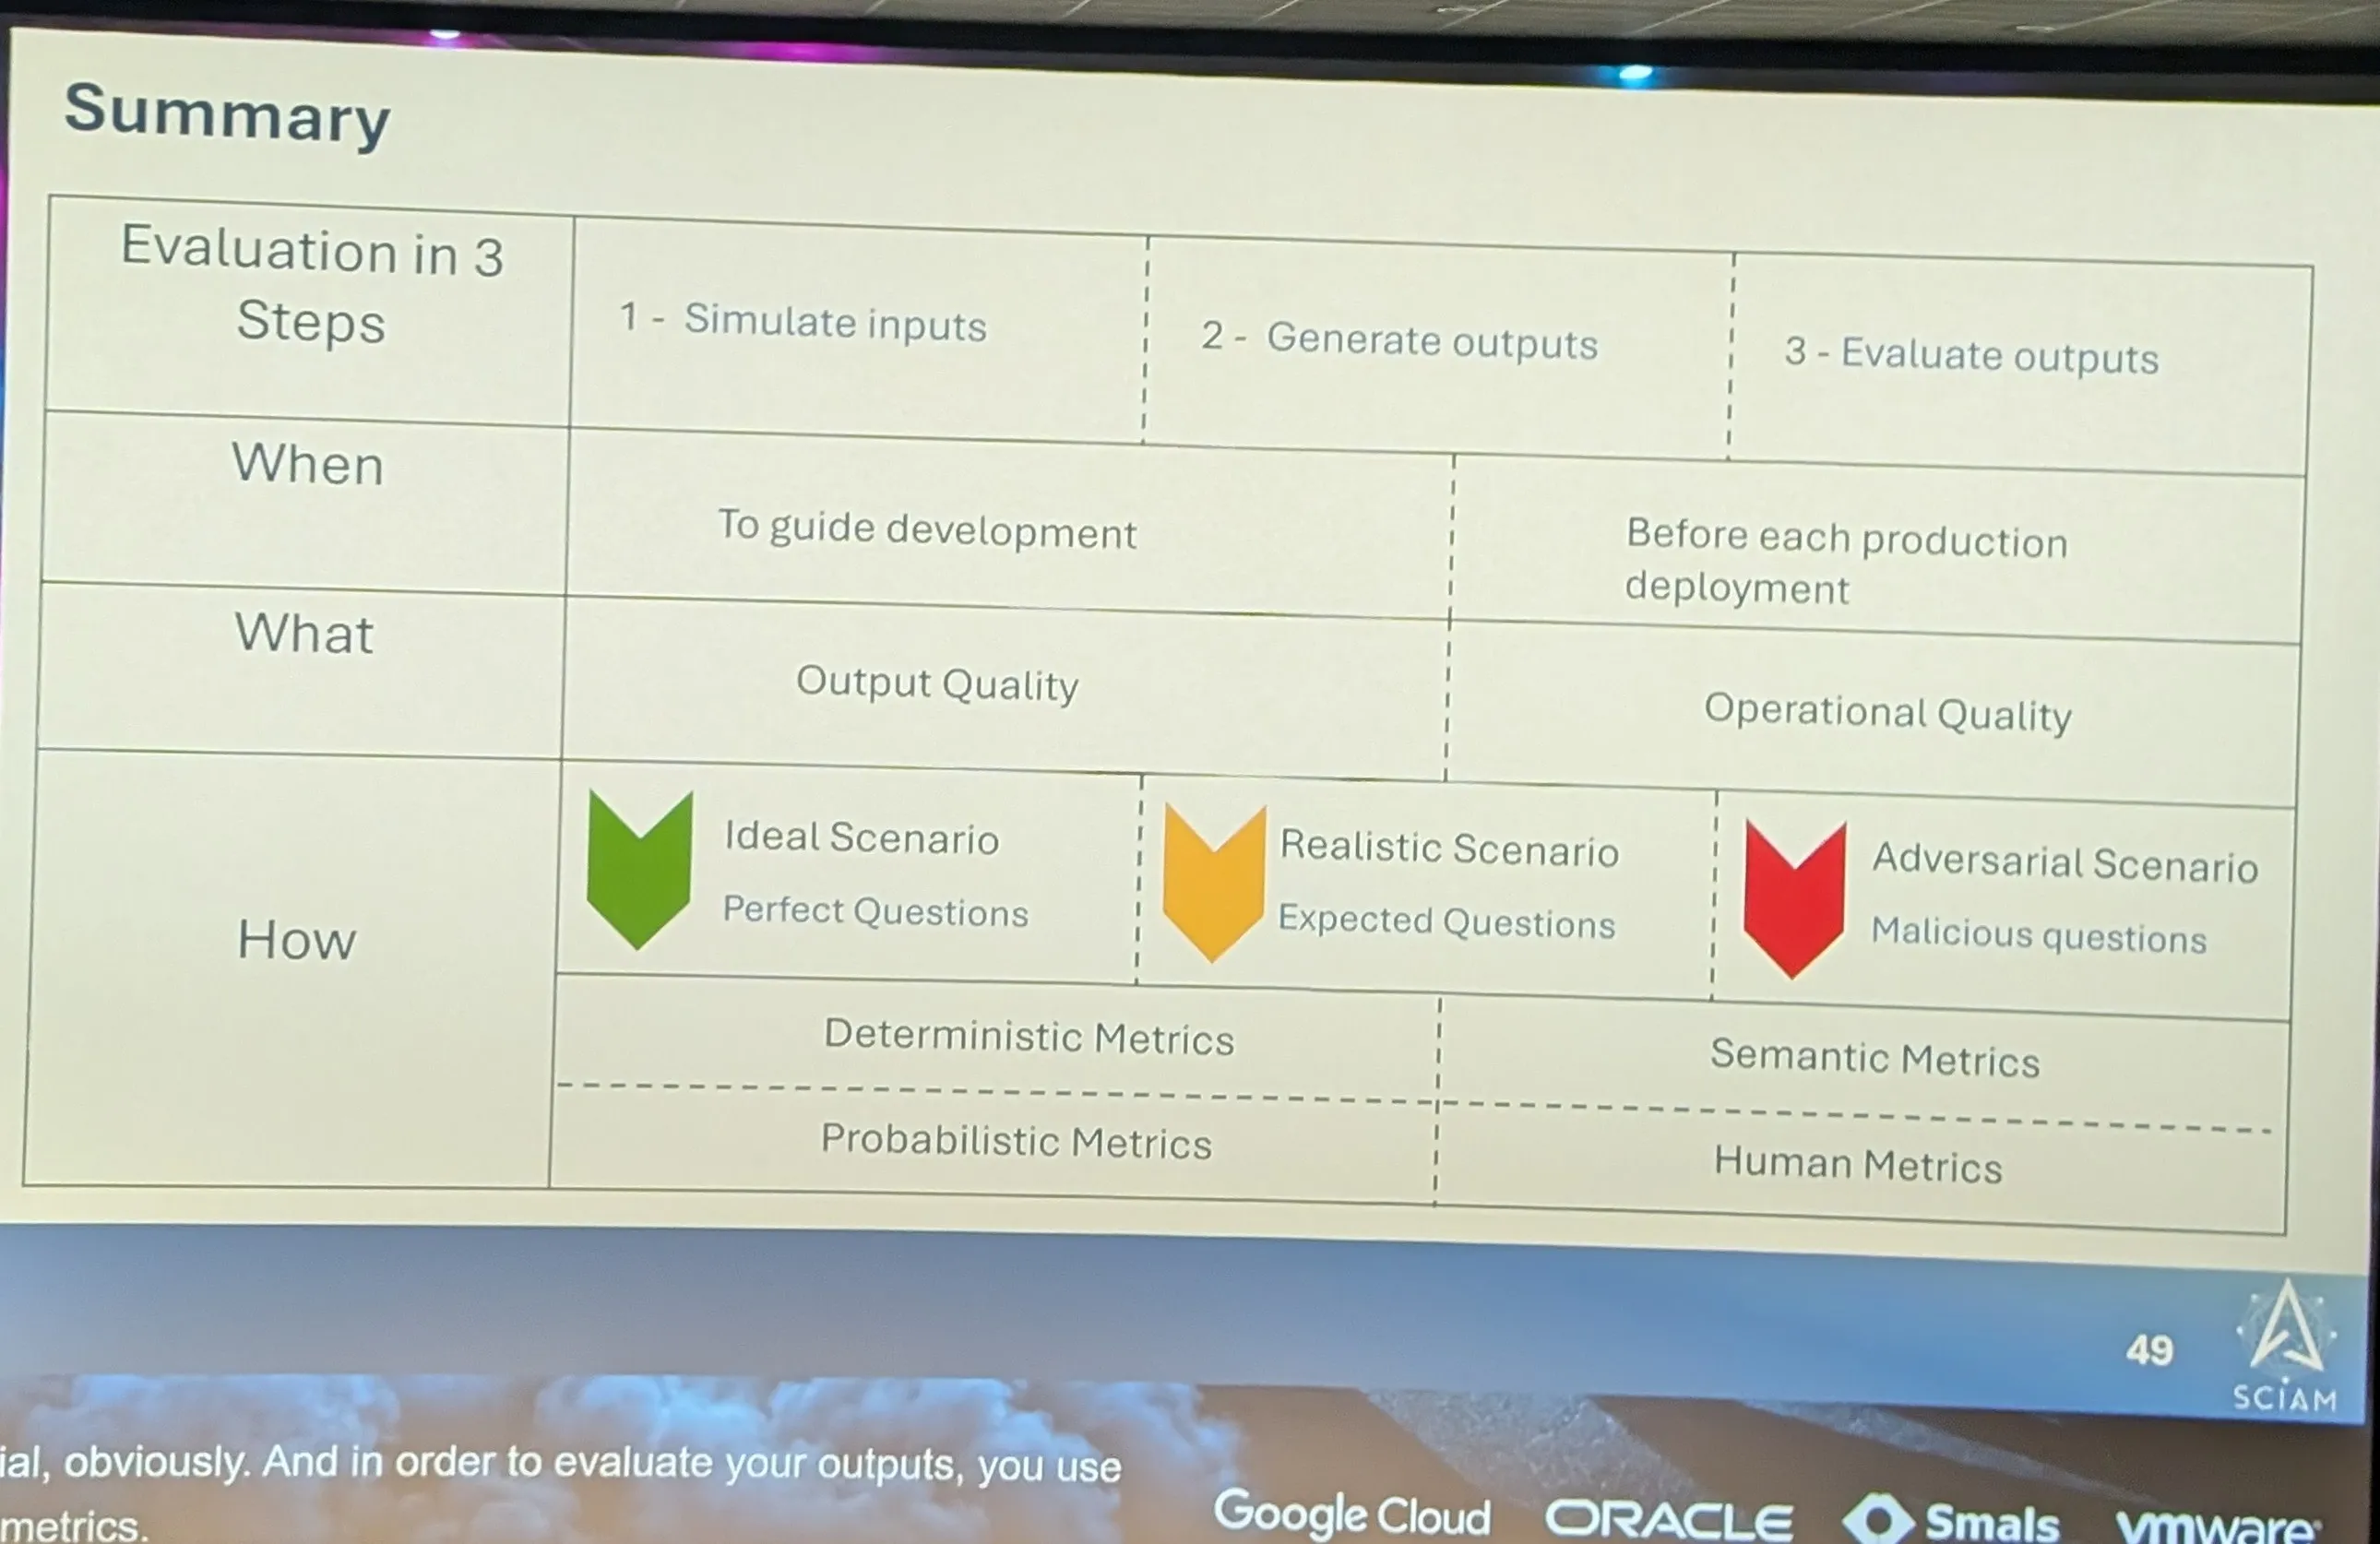
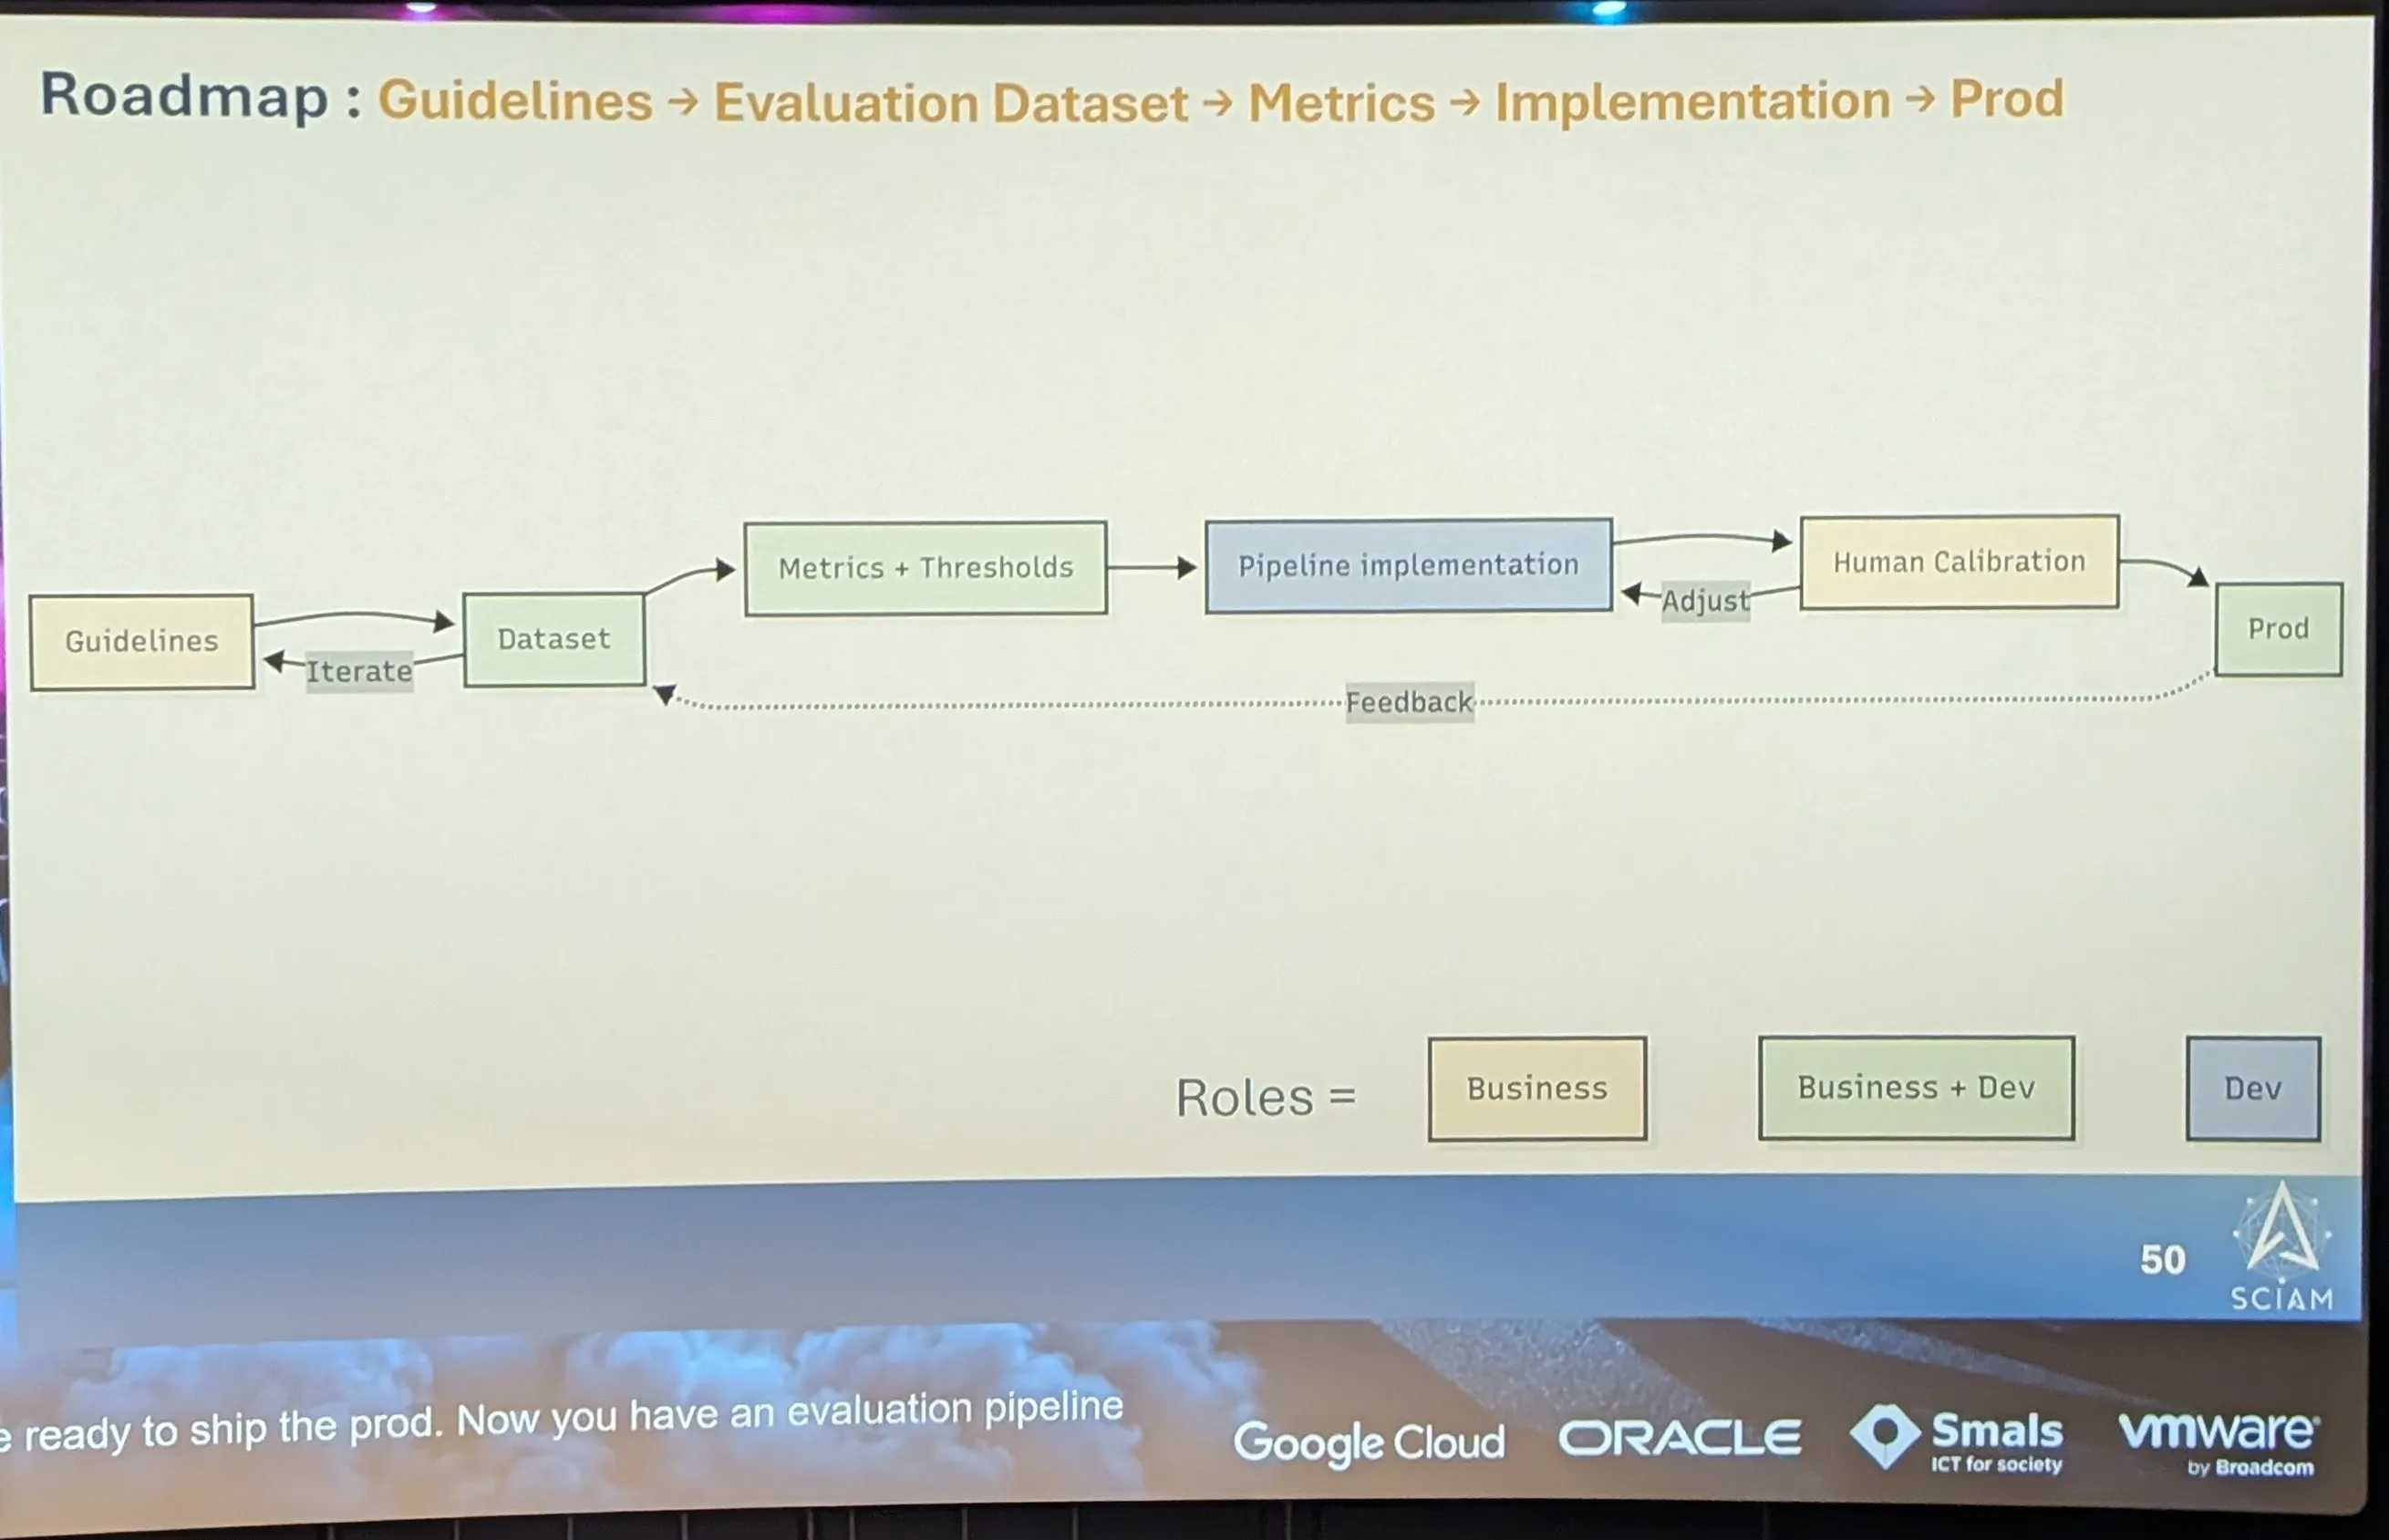
Section titled “Summary”This session explores how to evaluate generative AI systems reliably despite their unpredictability. Using a RAG chatbot case study, it covers adapting metrics for accuracy, coherence, and business value; the limits of traditional and LLM-as-a-judge methods; the role of human review; and continuous monitoring for drift.
Timeline
Section titled “Timeline”
Extra notes
Section titled “Extra notes”- Room 8 · Lunch Talk · 81 favourites
- How to evaluate a generative AI: metrics, limits of LLM-as-a-judge, the role of human review. Useful for an AI lead’s recurring question: how to measure what AI brings.